What this class covered
- An agent factory: a prompt plus a schema
- The RCA agent and the AI Verdict tab
- Flaky tests, scored with the DeFlaky CLI
- When each agent runs, and where its output lands
- The self-healer: suggestions, not fixes
- Tasks, and what comes next
- An agent is a prompt file plus an output schema.
createAgent()fills the placeholders, adds the schema to the system prompt, calls the LLM gateway and checks the reply with AJV. - The RCA agent runs after the run, in the custom reporter, once for each failed test (at most 10), and writes a root cause, a severity, a priority and fixes to the AI Verdict tab.
- A verdict reads the error, not the code: the prompt gets the title, file, error and stack. Check it against the spec before you act on it.
- A flaky test sometimes passes and sometimes fails. DeFlaky runs the suite several times, and its FlakeScore is the share of stable tests.
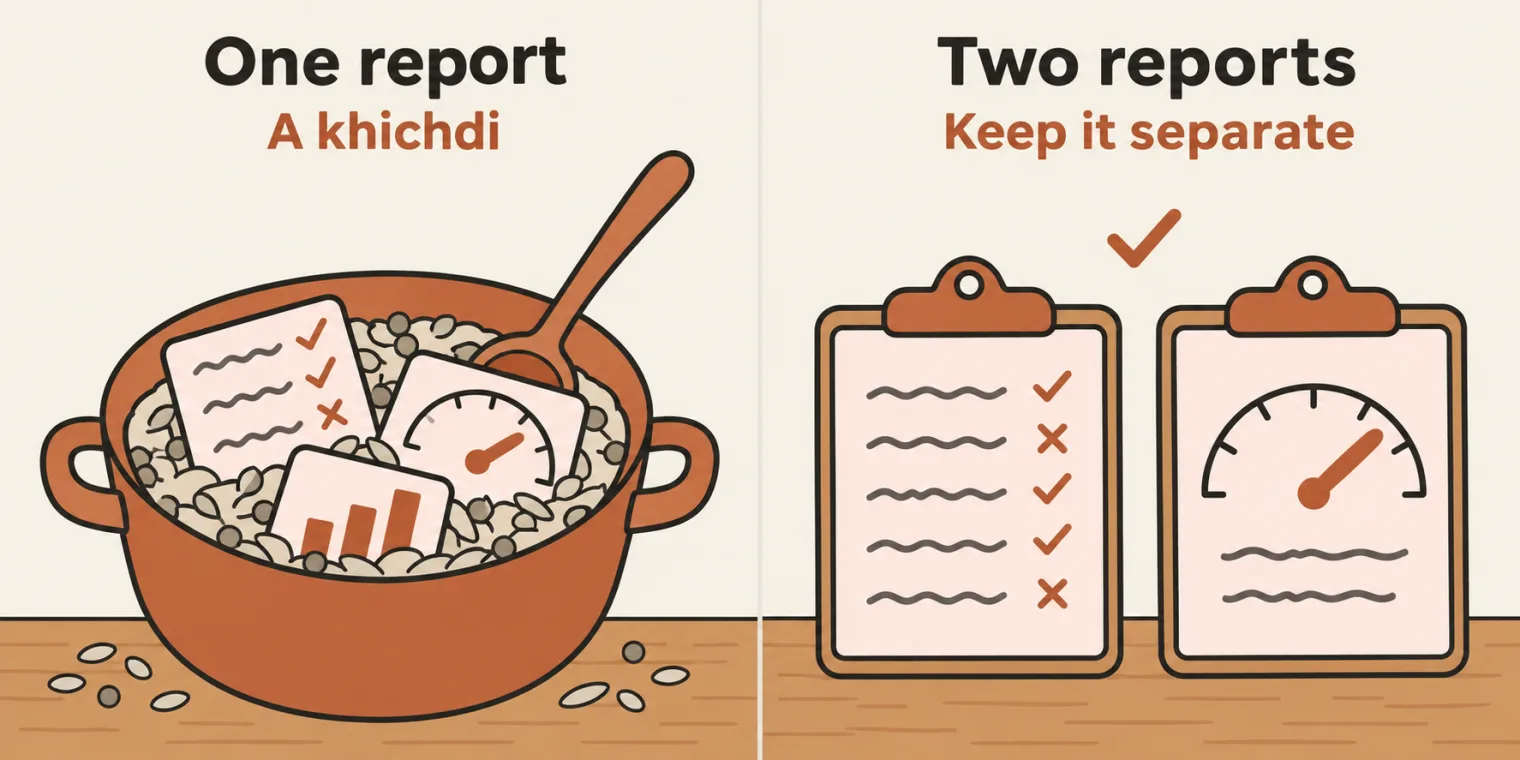
- Keep the flakiness report separate from the custom report, the instructor suggested: one report for everything becomes a khichdi.
- The self-healer only suggests. It checks each candidate on the page (one match, visible), and the test still fails; fixing and rerunning needs a separate LangChain agent.
- No key, no AI verdict: the reporter skips the RCA agent, and the agent's heuristic fallback covers a call that fails, not a missing key.
An agent factory: a prompt plus a schema
Where the last class stopped. The last class added the LLM gateway, on a different branch, llm-aiagents, and this class works on the same branch. Now the instructor wanted a few more agents: for example RCA, a flaky test case finder, and a self-healer. To make this better, the framework should work in such a way that we only add the prompt, and the rest of the things are taken care of by AI automatically. The deck's 14 November section opens the same way: a prompt, and the rest of the things will be done by AI automatically.
The objective. Add an AI layer to this Playwright framework, built around a provider-agnostic LLM client, which the class already has, and an agent factory, so that any new agent is a prompt plus an output schema rather than new plumbing. This is the new thing, the instructor said, and it will make your framework great. Whenever someone wants a new agent, they just add a new prompt. Add an RCA prompt and it becomes the RCA agent, attached to Playwright; something like bug triaging could run the same way, after the build. The deck's objective adds a working rule: plan first, then build one agent at a time, starting with the test-data generator, and stop after each for review.
The framework, with an AI layer. The framework the class built runs end-to-end tests, AI tests and API tests. The AI layer adds, first of all, the LLM gateway, also called the client. It is agnostic: you can use DeepSeek, OpenAI or anything else, whichever you want.
The prompt. With a screenshot of the custom report pasted in, the instructor gave the coding agent this prompt, and later said the prompt would be shared with the class. The deck holds it:
In the custom report lets add the 1. Data Generated by AI should be also appended to the AI Data Tab 2. AI Verdict, if there is failure, we can add a RCA here in this tab lets create a new test similar to e2e-checkout-failure.spec.ts and open the report custom(add 1 fail testcase into it deliberlty so that we can see the AI Verdict. lets keep the strurcute same Add an AI layer to this Playwright framework, built around a provider-agnostic
LLMClientor LLM gateway already created and an agent factory, so that any new agent is a prompt plus an output schema rather than new plumbing. go through the code first before creating new things, we already have a proper strcuture try to use the same and minium changes to achieve the same, we are also going to add the 2 more agents also Flaky TestCases and self healer points also after words.
The instructor also asked the coding agent for its plan, as an MD file in the learning folder. In the repo it is the plan. How many agents? Four, the instructor counted, and you can add five too. The plan names four: Test Data, RCA, a Flaky Analyzer and the Self-Healer. Its LLM summary for flaky tests is marked as next, so the flaky part built in this class is DeFlaky, beside the report's existing build-to-build comparison. The plan's table lists what it reused: the gateway, the report's existing tabs (AI Data, AI Verdict, Flaky, Self-Heal), the hasApiKey() switch and AJV, already a dependency since the JSON Schema class.
What is a factory? Based on the prompt, the instructor explained, the factory takes the prompt, for example an RCA prompt, and creates the agent automatically. To create any kind of agent, you need a name, a prompt, a system message, a temperature, and a schema. In the repo that is createAgent(), in src/ai/agents/agentFactory.ts:
export function createAgent<T>(spec: AgentSpec): Agent<T> {
    let validate: ValidateFunction | undefined;

    return {
        name: spec.name,
        async run(vars = {}) {
            const template = fs.readFileSync(path.join(PROMPTS_DIR, spec.prompt), 'utf8');
            // One pass, so values that themselves contain {{...}} are not substituted again.
            const prompt = template.replace(/\{\{(\w+)\}\}/g, (_, key: string) => {
                if (!(key in vars)) throw new Error(`[agent:${spec.name}] missing prompt variable {{${key}}}`);
                return String(vars[key]);
            });

            const system =
                (spec.system ? `${spec.system}\n\n` : '') +
                `Your JSON must match this JSON Schema:\n${JSON.stringify(spec.schema)}`;

            const { data } = await new LLMGateway(spec.gateway).askJson<T>(prompt, {
                system,
                temperature: spec.temperature,
                maxTokens: spec.maxTokens,
            });

            validate ??= ajv.compile(spec.schema);
            if (!validate(data)) {
                throw new Error(
                    `[agent:${spec.name}] output does not match schema: ${ajv.errorsText(validate.errors)}\n` +
                        JSON.stringify(data),
                );
            }

            if (spec.attachAs) await attachToCurrentTest(spec.attachAs, data);
            return data;
        },
    };
}
Lines 55 to 58 fill the {{PLACEHOLDERS}} in one pass and throw on a missing one. Lines 60 to 62 add the schema to the system prompt, so the model is told the exact shape to return. Line 64 calls the gateway; lines 70 to 76 check the reply with AJV and throw on a mismatch; line 78 attaches the output to the running test when attachAs is set.
The Test Data agent shows how small an agent is now: a prompt file, a schema, and one createAgent() call.
/**
 * Test data agents. Output is attached as 'ai-data', so it shows up in the
 * AI Data tab of the TTA report.
 */

import { createAgent } from './agentFactory';
import type { CheckoutCustomer } from '../../utils/DataGenerator';

/** Vars: FIRST_INITIAL, LAST_INITIAL, STATE (random values keep every customer different). */
export const checkoutCustomerAgent = createAgent<CheckoutCustomer>({
    name: 'checkout-customer',
    prompt: 'checkoutCustomer.prompt.md',
    temperature: 1,
    attachAs: 'ai-data',
    schema: {
        type: 'object',
        required: ['firstName', 'lastName', 'postalCode'],
        properties: {
            firstName: { type: 'string', minLength: 1 },
            lastName: { type: 'string', minLength: 1 },
            postalCode: { type: 'string', pattern: '^[0-9]{5}$' },
        },
    },
});
DataGenerator.checkoutCustomerAI(), from the last class, now calls checkoutCustomerAgent.run() with the same three Faker values, instead of building the request itself. Its output is attached as ai-data, which is how it reaches the report's AI Data tab. Code-wise, we are not concerned, the instructor said, and a Ponytail review would be added as well: the concern is the architecture.
What the factory checks. Run for these notes, offline. The class's RCA agent is built with this factory; here its gateway call is replaced by a fixed reply, so no model is called:
import { test } from '@playwright/test';
import { LLMGateway } from '../../ai/LLMGateway';
import { rcaAgent, analyzeFailure } from '../../ai/agents/rcaAgent.local';

// rcaAgent.local.ts is the class's rcaAgent.ts with line 29 changed, so its gateway points at a local model.
// Here no model is called: askJson() is replaced by a fixed reply.
test('what the agent factory checks and sends', async () => {
    // 1. A placeholder with no value: run() stops before any request.
    try {
        await rcaAgent.run({ TITLE: 'a test' });
    } catch (e) {
        console.log(`a missing variable:\n  ${(e as Error).message}`);
    }

    // 2. What the factory hands the gateway: the filled prompt, and the schema added to the system prompt.
    let reply: unknown = { rootCause: 'a stub', severity: 'medium', priority: 'P2', fixes: [] };
    let calls = 0;
    LLMGateway.prototype.askJson = async function (prompt: string, opts?: { system?: string }) {
        if (calls++ === 0) {
            console.log(`the prompt, line 3: ${prompt.split('\n')[2]}`);
            console.log(`the system prompt:\n  ${opts?.system?.split('\n').join('\n  ')}`);
        }
        return { data: reply } as never;
    };
    const vars = { TITLE: 'a test', FILE: 'a.spec.ts:1', ERROR: 'Error: boom', STACK: 'n/a' };
    console.log(`run() returns: ${JSON.stringify(await rcaAgent.run(vars))}`);

    // 3. A reply that breaks the schema: run() throws, and analyzeFailure() falls back to its heuristic.
    reply = { rootCause: 'a stub', severity: 'critical', fixes: 'retry' };
    try {
        await rcaAgent.run(vars);
    } catch (e) {
        console.log(`a reply that breaks the schema:\n  ${(e as Error).message.split('\n').join('\n  ')}`);
    }
    const verdict = await analyzeFailure({ title: 'a test', file: 'a.spec.ts:1', error: 'Error: boom' });
    console.log(`analyzeFailure() returns: ${JSON.stringify(verdict)}`);
});
Running 1 test using 1 worker

a missing variable:
  [agent:rca] missing prompt variable {{FILE}}
the prompt, line 3: Test: a test
the system prompt:
  You are a senior SDET who debugs Playwright test failures.

  Your JSON must match this JSON Schema:
  {"type":"object","required":["rootCause","severity","priority","fixes"],"properties":{"rootCause":{"type":"string","minLength":1},"severity":{"enum":["low","medium","high"]},"priority":{"enum":["P0","P1","P2","P3"]},"fixes":{"type":"array","items":{"type":"string"}}}}
run() returns: {"rootCause":"a stub","severity":"medium","priority":"P2","fixes":[]}
a reply that breaks the schema:
  [agent:rca] output does not match schema: data must have required property 'priority', data/severity must be equal to one of the allowed values, data/fixes must be array
  {"rootCause":"a stub","severity":"critical","fixes":"retry"}
RCA agent: LLM unavailable, using heuristic verdict ([agent:rca] output does not match schema: data must have required property 'priority', data/severity must be equal to one of the allowed values, data/fixes must be array)
analyzeFailure() returns: {"rootCause":"Error: boom","severity":"medium","priority":"P2","fixes":["Open the trace to inspect the failing action"]}
  ✓  1 [chromium] › src/tests/aiTests/agent-factory.checks.spec.ts:7:5 › what the agent factory checks and sends (23ms)

  1 passed (285ms)
A missing placeholder stops the run before any request. The system prompt carries the schema. A reply that breaks the schema throws, with AJV's error list and the raw JSON, and analyzeFailure() catches that and falls back to a guess from the error text. Its warning says the LLM is unavailable for any error, a schema mismatch included.
The RCA agent and the AI Verdict tab
What RCA means. RCA is root cause analysis, the instructor answered. Say 100 tests run and 2 fail: in the custom report, those 2 failures get AI inputs, why they failed and how we can fix them. Whenever there is a failure, those inputs are there to debug or fix the test. RCA runs when you have the results: a Playwright run leaves data on how many tests passed, how many failed, and logs, and the instructor showed it in the TTA report and in the JSON files around the test results.
Two tabs. The class ran the last class's test again, with a DeepSeek key created again on screen, and opened the custom report. It already had an AI Verdict tab, but there was no failure, and the data generated by AI was not added to the report. So the instructor asked for two things: the data generated by AI goes into the AI Data tab, because we want to see which data was created by AI, and when there is a failure, an RCA goes into the tab called AI Verdict.
A deliberate failure. Why add a failing test? Because, the instructor asked and answered, we have to see the AI verdict. The new spec, e2e-checkout-failure.spec.ts, has two tests: a checkout with an AI-generated customer, and this one, which fails on purpose:
    // DELIBERATE FAILURE: one item is added but two are expected, to demo the AI Verdict tab.
    test('should show two items in cart (deliberately fails)', async ({ page, validLogin, inventoryPage, cartPage }) => {
        await visualStep(page, 'Inventory page: add first item to cart', async () => {
            await inventoryPage.assertLoaded();
            await inventoryPage.addToCart(FIRST_ITEM_ID);
        });

        await visualStep(page, 'Cart page: expect two items in cart', async () => {
            await cartPage.open();
            expect(await cartPage.rowCount(), 'cart row count').toBe(2);
        });
    });
Line 57 adds one item, and line 62 expects two rows.
The class's run. That run is in the TTA reports left in the instructor's local folder. In the report from 07:17, the AI Data tab held the customer the Test Data agent generated: Xavier Vaughn, with the ZIP code 23219. For a passed test, do we need anything at all? A screenshot, the report and the video, and that's it, was the answer in class. For the failure, we expected two items but got one, and the AI Verdict tab gave the verdict. DeepSeek figured out that it is an intentional failure, the instructor said, not a locator or anything like that. The verdict, from that report:
Severity: medium
Priority: P3
Root cause: The test is explicitly named 'deliberately fails' and asserts a cart row count of 2 while the application actually renders 1 row, so the mismatch is intentional (a seeded negative test) rather than a real product defect. The assertion at e2e-checkout-failure.spec.ts:62 is hard-coded to an expected value that does not match the actual cart state produced by the AI-generated data.
How to fix:
- If this spec is meant to demonstrate failure detection, mark it with test.fixme() or test.skip() and annotate it as an intentional negative test so it does not pollute CI results.
- If it should pass, correct the expected value at e2e-checkout-failure.spec.ts:62 to match the real cart contents, or fix the setup step that should add the second item before the assertion.
- Verify the AI-generated test data actually adds two distinct products to the cart; log the cart contents before the assertion to confirm whether the app or the data is wrong.
- Move the assertion out of the visualStep wrapper (visualSteps.ts:35) or ensure the wrapper does not mask the underlying count, so failures point directly at the assertion line.
A failure can be due to a locator, or due to an environment variable too, the instructor said. If it is related to a locator, it can go to the self-healer.
The prompt. The verdict comes from this prompt. The instructor read it out: here is the test, the file, the error log and the stack trace; give me the root cause, the severity and priority, and the fixes. Prompts differ, the instructor said: you can change it according to your company.
A Playwright test failed. Find the most likely root cause and how to fix it.

Test: {{TITLE}}
File: {{FILE}}

Error:
{{ERROR}}

Stack (may be truncated):
{{STACK}}

Rules:
- rootCause: one or two plain sentences on WHY it failed (product bug, test bug, data, environment, timing), not a restatement of the error.
- severity: "high" if a core user flow is broken, "medium" for a wrong assertion or test bug, "low" for cosmetic issues.
- priority: P0 to P3, P0 being the most urgent.
- fixes: 1 to 4 concrete, actionable steps, naming the file or line when the stack shows it.
The agent. rcaAgent.ts is one createAgent() call with that prompt and a schema for the four fields, plus analyzeFailure(), which tries the agent and falls back to a heuristic:
export const rcaAgent = createAgent<RcaVerdict>({
    name: 'rca',
    prompt: 'rca.prompt.md',
    system: 'You are a senior SDET who debugs Playwright test failures.',
    temperature: 0,
    schema: {
        type: 'object',
        required: ['rootCause', 'severity', 'priority', 'fixes'],
        properties: {
            rootCause: { type: 'string', minLength: 1 },
            severity: { enum: ['low', 'medium', 'high'] },
            priority: { enum: ['P0', 'P1', 'P2', 'P3'] },
            fixes: { type: 'array', items: { type: 'string' } },
        },
    },
});

export async function analyzeFailure(input: FailureInput): Promise<RcaVerdict> {
    try {
        return await rcaAgent.run({
            TITLE: input.title,
            FILE: input.file,
            ERROR: input.error.slice(0, 3000),
            STACK: (input.stack ?? 'n/a').slice(0, 3000),
        });
    } catch (e) {
        console.warn(`RCA agent: LLM unavailable, using heuristic verdict (${(e as Error).message.split('\n')[0]})`);
        return heuristicVerdict(input);
    }
}
Who calls it. It is not an independent AI agent, the instructor said: it runs immediately after your Playwright tests, when there is a failure. Nothing changed in the Playwright configuration for it: screenshot on, video on, the base URL and the custom reporter were already there. It runs because of the custom reporter. In the custom reporter, there is an array that collects the failures, and the instructor read out the comment above the code responsible:
    // RCA AI agent: analyze each failed test via the LLM gateway and store a verdict.
    private async runRcaAnalysis(): Promise<void> {
        const failures = this.testResults.filter(
            (t) => t.status === 'failed' || t.status === 'timedOut',
        );
        if (failures.length === 0) return;
        if (!hasApiKey()) {
            console.log('🤖 RCA agent: no LLM API key set - skipping AI verdict.');
            return;
        }

        const cap = 10;
        const toAnalyze = failures.slice(0, cap);
        if (failures.length > cap) {
            console.log(`🤖 RCA agent: analyzing first ${cap} of ${failures.length} failures.`);
        } else {
            console.log(`🤖 RCA agent analyzing ${toAnalyze.length} failure(s)...`);
        }

        for (const t of toAnalyze) {
            try {
                const verdict = await analyzeFailure({
                    title: t.fullTitle,
                    file: t.location,
                    error: t.error ?? 'Unknown error',
                    stack: t.errorStack,
                });
                this.aiVerdicts.push({ test: t.fullTitle, file: t.location, verdict });
            } catch (e) {
                console.warn(`RCA failed for ${t.title}: ${(e as Error).message}`);
            }
        }
    }
This method came with the framework's first commit, on 20 October, as the repo's history shows. What this class changed is analyzeFailure(): it used to be a stub that only guessed from the error text, and now it asks the LLM through the factory.
The same failures, a local model. Run for these notes: the class's two failures, exactly as the reporter passed them to the agent in class (the deliberate one above, and the flaky test's, below), through a copy of rcaAgent.ts whose line 29 also passes the factory's gateway option, pointed at Ollama on a local machine:
temperature: 0, gateway: { provider: 'openai', baseUrl: 'http://127.0.0.1:11434/v1', apiKey: 'ollama', model: 'gpt-oss:20b' },
import type { FailureInput } from '../../ai/agents/rcaAgent';

// The class's two failures, as the reporter passed them to analyzeFailure() in class: the title and file from
// the AI Verdict card, the error and stack from the error box of the same report. Only the stack's folder
// prefix is removed, so its paths read from the repo root.

export const DELIBERATE: FailureInput = {
    "title": "chromium › aiTests/e2e-checkout-failure.spec.ts › @AI E2E @Checkout Checkout with AI data and RCA › should show two items in cart (deliberately fails)",
    "file": "e2e-checkout-failure.spec.ts:54",
    "error": "Error: cart row count\n\nexpect(received).toBe(expected) // Object.is equality\n\nExpected: 2\nReceived: 1",
    "stack": "Error: cart row count\n\nexpect(received).toBe(expected) // Object.is equality\n\nExpected: 2\nReceived: 1\n    at src/tests/aiTests/e2e-checkout-failure.spec.ts:62:65\n    at src/utils/visualSteps.ts:36:9\n    at visualStep (src/utils/visualSteps.ts:35:5)\n    at src/tests/aiTests/e2e-checkout-failure.spec.ts:60:9"
};

export const FLAKY: FailureInput = {
    "title": "chromium › aiTests/e2e-checkout-flaky.spec.ts › @Flaky E2E @Checkout Checkout flakiness demo › should show the expected items in cart (flaky)",
    "file": "e2e-checkout-flaky.spec.ts:57",
    "error": "Error: cart row count\n\nexpect(received).toBe(expected) // Object.is equality\n\nExpected: 2\nReceived: 1",
    "stack": "Error: cart row count\n\nexpect(received).toBe(expected) // Object.is equality\n\nExpected: 2\nReceived: 1\n    at src/tests/aiTests/e2e-checkout-flaky.spec.ts:67:65\n    at src/utils/visualSteps.ts:36:9\n    at visualStep (src/utils/visualSteps.ts:35:5)\n    at src/tests/aiTests/e2e-checkout-flaky.spec.ts:65:9"
};
import { test } from '@playwright/test';
import { analyzeFailure } from '../../ai/agents/rcaAgent.local';
import { DELIBERATE, FLAKY } from './class-failure';

// rcaAgent.local.ts is the class's rcaAgent.ts with line 29 changed, so its gateway calls a local model.
test("the RCA agent on the class's two failures, local model", async () => {
    test.setTimeout(900_000);
    for (const [name, failure] of [['the deliberate failure', DELIBERATE], ['the flaky test', FLAKY]] as const) {
        const verdict = await analyzeFailure(failure);
        console.log(`${name}:\n${JSON.stringify(verdict, null, 2)}`);
    }
});
Running 1 test using 1 worker

18:38:30 [info] [LLMGateway] -> openai/gpt-oss:20b (1129 chars, json)
18:38:48 [info] [LLMGateway] <- openai/gpt-oss:20b 17339ms (in 933 / out 160 tokens)
the deliberate failure:
{
  "rootCause": "The test expects two items in the cart but only one is added - likely because the AI integration or test data does not provide a second product for the cart.",
  "severity": "high",
  "priority": "P0",
  "fixes": [
    "Update src/tests/aiTests/e2e-checkout-failure.spec.ts line 54 to correctly trigger addition of a second item (verify AI prompt and expected response).",
    "Ensure that the AI service returns two distinct items by checking the request payload in src/utils/visualSteps.ts lines 35-36. If necessary, adjust the AI prompt or mock response to include a second product.",
    "Verify that the cart page renders multiple rows; if only one row is displayed due to a rendering bug, fix the component logic in the cart view."
  ]
}
18:38:48 [info] [LLMGateway] -> openai/gpt-oss:20b (1114 chars, json)
18:38:56 [info] [LLMGateway] <- openai/gpt-oss:20b 8749ms (in 902 / out 142 tokens)
the flaky test:
{
  "rootCause": "The cart items are not fully rendered when the count is asserted, causing a timing race condition that makes the test flaky.",
  "severity": "medium",
  "priority": "P2",
  "fixes": [
    "Add an explicit wait for the cart rows to be visible or for their count to equal 2 before performing the assertion in e2e-checkout-flaky.spec.ts (around line 67).",
    "Use Playwright’s expect(locator).toHaveCount(2) instead of a manual count check, ensuring the test waits until two rows are present.",
    "Modify visualSteps.ts at line 36 to include a wait for the cart table or its rows before taking the screenshot and asserting the count."
  ]
}
  ✓  1 [chromium] › src/tests/aiTests/rca.local.spec.ts:6:5 › the RCA agent on the class's two failures, local model (26.1s)

  1 passed (26.4s)
The logger's dates are removed. Every request the run made was logged, and there were two, both POSTs to Ollama's /v1/chat/completions on 127.0.0.1. The local model, gpt-oss:20b (20.9 billion parameters, as Ollama reports it), did not take the title's "deliberately fails" as the answer: it blamed the AI integration or the test data, at severity high and P0, where DeepSeek in class called the failure intentional, at medium and P3. For the flaky test, it blamed a timing race, and so did DeepSeek in the class's run of that test at 07:33: "The test asserts the cart row count immediately after adding items, but the cart UI updates asynchronously, so the assertion runs before the second item has rendered."
A verdict reads the error, not the code. The prompt gives the model the title, the file, the error and the stack (lines 3 to 10), never the spec itself. The flaky test's real cause is in the spec: line 58 draws the expected count at random, and only one item is ever added. Treat a verdict as a lead, and check it against the code before you act on it.
With no key. Run for these notes, offline: the class's RCA agent, then the class's reporter, on the same deliberate failure, with no LLM key set anywhere:
import { test } from '@playwright/test';
import fs from 'fs';
import { analyzeFailure } from '../../ai/agents/rcaAgent';
import CustomTTAReporter from '../../utils/CustomReporter';
import { DELIBERATE } from './class-failure';

// No LLM key anywhere. First the RCA agent itself, then the class's reporter, on the class's deliberate failure.
test('no key: the RCA agent, then the reporter', async () => {
    console.log('1. analyzeFailure():');
    console.log(JSON.stringify(await analyzeFailure(DELIBERATE), null, 2));

    console.log('2. the reporter, with the same failure:');
    const now = new Date();
    const failed = {
        id: '1', title: 'should show two items in cart (deliberately fails)', fullTitle: DELIBERATE.title,
        file: 'aiTests/e2e-checkout-failure.spec.ts', describePath: [], location: DELIBERATE.file, duration: 0,
        status: 'failed' as const, retry: 0, screenshots: [], steps: [], logs: [], tags: [],
        error: DELIBERATE.error, errorStack: DELIBERATE.stack,
    };
    const file = await new CustomTTAReporter().renderExternalRun({
        runId: 'notes', startTime: now, endTime: now, tests: [failed],
        stats: { total: 1, passed: 0, failed: 1, skipped: 0, flaky: 0 },
    });
    const tab = fs.readFileSync(file, 'utf8').match(/<div id="tab-verdict" class="main-tab-panel">\s*<div class="ai-empty">(.*?)<\/div>/s);
    console.log(`AI Verdict tab: ${tab?.[1]}`);
});
Running 1 test using 1 worker

1. analyzeFailure():
RCA agent: LLM unavailable, using heuristic verdict (No LLM provider configured. Set one of GROQ_API_KEY, OPENROUTER_API_KEY, DEEPSEEK_API_KEY, OPENAI_API_KEY, ANTHROPIC_API_KEY in .env (and optionally LLM_PROVIDER).)
{
  "rootCause": "Error: cart row count",
  "severity": "medium",
  "priority": "P2",
  "fixes": [
    "Open the trace to inspect the failing action"
  ]
}
2. the reporter, with the same failure:
🤖 RCA agent: no LLM API key set - skipping AI verdict.
🔁 Flaky analyzer: only one build recorded - run again to compare.
AI Verdict tab: ⚖️ No AI verdicts - no failures analyzed in this run.
  ✓  1 [chromium] › src/tests/aiTests/rca.no-key.spec.ts:8:5 › no key: the RCA agent, then the reporter (11ms)

  1 passed (272ms)
The em dashes in the reporter's messages are shown as hyphens. The agent's fallback is a guess from the error text: "strict mode violation" or "timeout" pick a known cause, and anything else, like this failure, returns the error's first line. The reporter never gets that far without a key: line 520 checks for one first and skips the agent, so the AI Verdict tab stays empty. The fallback covers an LLM call that fails, not a missing key; the header of rcaAgent.ts, which says the tab is never empty for a failure, holds only once a key is set.
Allure? Asked how an organization that uses the Allure report can link this: very easy, the instructor said. You can customize that report, or create the RCA as a separate HTML report and append it to the Allure report, which has a way to append it.
Flaky tests, scored with the DeFlaky CLI
What a flaky test is. The first build runs 100 tests: 97 pass and 3 fail. Run the build again, the 3 tests: 2 fail again and 1 passes. Then 1 test is flaky in nature, the culprit: sometimes it passes, and sometimes it fails.
DeFlaky. The ideal way to find a flaky test is a free library, the instructor said, and the easiest is DeFlaky: a 100% free CLI. You install it and run your tests through it, and it works out the flaky score. A free account on its dashboard is optional, or you can create your own solution on the same idea. DeFlaky is the instructor's own tool: 100% free, open source, MIT licensed, already available, and installed with npm, so you do not have to create it from scratch. The README links DeFlaky, and the deck links its docs. The repo's DeFlaky note warns that the docs describe a newer deflaky-cli, where -t is a threshold: trust deflaky run --help for the version you have.
The prompt. Run the tests two times to check the flakiness via the DeFlaky CLI, push the data to the dashboard, and put the dashboard's API key in .env. The deck holds it:
Can we run the testcase 2 times to check the flkyness via the deflaky cli. https://deflaky.com/docs usage - deflaky run -c "npx playwright test" -r 5 --push -t API_KEY api key i have added alredy in the .evn file and create a new tc in e2e-checkout-flaky.spec.ts in the same aiTestFolder and push the data to deflaky dashbaord so taht we can see the flaky score.
The flaky spec. e2e-checkout-flaky.spec.ts has a stable checkout test and this one:
    // DELIBERATE FLAKE: the expected count is random, standing in for shared test
    // data that another run left behind. Do not copy this pattern into real tests.
    test('should show the expected items in cart (flaky)', async ({ page, validLogin, inventoryPage, cartPage }) => {
        const expectedRows = Math.random() < 0.5 ? 1 : 2;

        await visualStep(page, 'Inventory page: add first item to cart', async () => {
            await inventoryPage.assertLoaded();
            await inventoryPage.addToCart(FIRST_ITEM_ID);
        });

        await visualStep(page, `Cart page: expect ${expectedRows} item(s) in cart`, async () => {
            await cartPage.open();
            expect(await cartPage.rowCount(), 'cart row count').toBe(expectedRows);
        });
    });
Line 58 draws the expected count, 1 or 2, at random, while line 62 adds one item, so about half the runs fail. The spec's header, lines 4 to 6, says DeFlaky reports such a test as flaky and lowers the FlakeScore.
What DeFlaky reads. It does not read Playwright's console output: after each run it scans test-results/ and similar folders for JSON or XML reports, the repo's note says, and Playwright writes none by default. So the commit added a JSON reporter to the config, line 53:
  reporter: [
    ['line'],
    ['html', { open: 'never' }],
    /* TTA custom report, written to tta-report/ (index.html always points to the latest run). */
    ['./src/utils/CustomReporter.ts'],
    /* JSON results for the DeFlaky CLI, which scans test-results/ after each run. */
    ['json', { outputFile: 'test-results/results.json' }],
  ],
The wrapper. npm run flaky runs src/utils/deflakyRun.js:
/**
 * Runs a spec N times through the DeFlaky CLI, pushes to the DeFlaky dashboard,
 * then copies the result into the TTA report's Flaky tab.
 *
 *   npm run flaky                                        # flaky demo spec, 2 runs
 *   npm run flaky -- src/tests/aiTests/e2e-checkout-flaky.spec.ts 5
 *
 * Why a wrapper: DeFlaky writes .deflaky/last-run.json only after ALL runs end,
 * but the TTA report is written during the last run. So the data is copied to
 * tta-report/deflaky-data.js afterwards, and the report loads it from there.
 */
require('dotenv').config({ quiet: true });
const fs = require('fs');
const { spawnSync } = require('child_process');

const spec = process.argv[2] || 'src/tests/aiTests/e2e-checkout-flaky.spec.ts';
const runs = process.argv[3] || '2';
const token = process.env.DEFLAKY_TOKEN || process.env.DEFLAKY_API_KEY || '';

const args = ['run', '-c', `npx playwright test ${spec} --project=chromium`, '-r', runs];
if (token) args.push('--push');
else console.warn('DEFLAKY_API_KEY not set: running locally without --push.');

const result = spawnSync('deflaky', args, { stdio: 'inherit', env: { ...process.env, DEFLAKY_TOKEN: token } });
if (result.error) {
    console.error(`Could not start deflaky (${result.error.message}). Install it: npm install -g deflaky-cli`);
    process.exit(1);
}

const source = '.deflaky/last-run.json';
if (fs.existsSync(source)) {
    fs.mkdirSync('tta-report', { recursive: true });
    fs.writeFileSync('tta-report/deflaky-data.js', `window.DEFLAKY_DATA = ${fs.readFileSync(source, 'utf8')};\n`);
    console.log('DeFlaky results added to the TTA report Flaky tab: open tta-report/index.html');
}
process.exit(result.status ?? 1);
It loads the token from .env (line 18), runs the spec through DeFlaky, 2 runs by default (line 17), pushes only when a token is set (line 21), then copies DeFlaky's result to tta-report/deflaky-data.js (lines 30 to 35). Lines 8 to 10 say why a wrapper: DeFlaky writes its result only after all runs end, and the TTA report is written during the last run.
The class's run. Two runs, pushed to the dashboard. The repo's DeFlaky note gives the output to expect: 2 tests, 1 stable, 1 flaky, 0 failing, a FlakeScore of 50.0%, and the results pushed. The class's own result, in the instructor's local folder, matches it: 2 runs, saved at 07:41, a FlakeScore of 50%: the stable test passed both runs, and the flaky test passed one of the two.
The dashboard, and a local report. On the dashboard, the data came and went, which the instructor called strange; there is a bug, the instructor thought. But DeFlaky works 100% local on your system, the instructor said: the platform is only for when you want to push the data. If you do not, a free local report is also created, and the class opened it on a local port: the repo's note gives deflaky serve -p 3333, then http://localhost:3333. The result the instructor read out: run two times, one test stable and one flaky. In the note's words, deflaky serve with a token turns on AI analysis in the local page, and that sends the results to deflaky.com.
FlakeScore. If there is flakiness, should the score increase or decrease? Decrease, the instructor said. DeFlaky's FlakeScore is the share of stable tests: a test that passes every run is stable, one that fails every run is failing, anything in between is flaky, and the score is stable tests divided by all tests, times 100 (DeFlaky's own analyzer, in the CLI the class used). One stable test out of two gives the class's 50%.
Run for these notes. The class's wrapper, with no token, on a stand-in for the flaky spec that opens no browser and signs in nowhere. Its flaky test draws the expected count the way line 58 does:
import { test, expect } from '@playwright/test';

// A stand-in for e2e-checkout-flaky.spec.ts that opens no browser and signs in nowhere. The cart holds one row,
// as in the class's spec, and the flaky test draws its expected count the way that spec's line 58 does.
const cartRowCount = () => 1;

test.describe('@Flaky stand-in, no browser', () => {
    test('stand-in, stable: expects the one row the cart holds', () => {
        expect(cartRowCount()).toBe(1);
    });

    test('stand-in, flaky: expects 1 or 2 rows at random', () => {
        const expectedRows = Math.random() < 0.5 ? 1 : 2;
        expect(cartRowCount(), 'cart row count').toBe(expectedRows);
    });
});
node src/utils/deflakyRun.js src/tests/aiTests/flaky-standin.spec.ts 5
DEFLAKY_API_KEY not set: running locally without --push.

  DeFlaky - Flaky Test Detector v1.0.0
  Running "npx playwright test src/tests/aiTests/flaky-standin.spec.ts --project=chromium" x5 times


━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
  DeFlaky - Flaky Test Report
━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━

  Summary
  Total tests:    2
  Stable tests:   1
  Flaky tests:    1
  Failing tests:  0

  FlakeScore:     50.0%  ██████████░░░░░░░░░░

  Flaky Tests

┌──────────────────────────────┬─────────────────────────┬────────────┬───────┬───────┬───────┐
│ Test                         │ File                    │ Pass Rate  │ Pass  │ Fail  │ Runs  │
├──────────────────────────────┼─────────────────────────┼────────────┼───────┼───────┼───────┤
│ [chromium] stand-in, flaky:… │ aiTests/flaky-standin.… │ 80%        │ 4     │ 1     │ 5     │
└──────────────────────────────┴─────────────────────────┴────────────┴───────┴───────┴───────┘

━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━

  Results saved to .deflaky/last-run.json
  Run `deflaky serve` to view the dashboard

DeFlaky results added to the TTA report Flaky tab: open tta-report/index.html
With no token, the wrapper ran DeFlaky without --push, and every request was logged: there were none. The same command, three times in a row:
| Round | Stand-in flaky test passed | FlakeScore | DeFlaky's verdict on it |
|---|---|---|---|
| 1 | 4 of 5 | 50% | flaky |
| 2 | 3 of 5 | 50% | flaky |
| 3 | 5 of 5 | 100% | stable |
Round 3 missed the flake: five passes in a row, which a test that fails half the time does about once in 32 tries. The repo's DeFlaky note calls 5 runs more reliable than 2 for the same reason: a 50% flake can pass 2 runs in a row. And retries must stay 0 for these runs, the plan says: otherwise Playwright retries the flake, and DeFlaky sees fewer failures. The config retries twice on CI (line 43).
Questions from the class. Will it work if you run in parallel? Yes, the instructor said: in parallel or sequential, whatever. If there is no failure in the first build, will DeFlaky still run? DeFlaky will always execute, but it will not report a flaky test: it will say all of them passed, with no flaky test: zero, 0%. In DeFlaky's own report, that is zero flaky tests and a FlakeScore of 100%, as round 3 shows. Can we get the RCA for a flaky test too? You can, the instructor said: DeFlaky was actually created because we want to do the RCA of a flaky test.
Into the custom report? A learner asked for DeFlaky's data in the custom report, and the instructor had it added: a function in the custom reporter appends it, and the Flaky tab showed the flaky test, marked red, with its flaky score. But this is too much, the instructor said: ideally there should be a separate report for flakiness, one that can be shared with QAs. Put everything in one report and you are creating a khichdi. So the suggestion: keep it as a separate report.
The commands. The instructor also asked the coding agent to put the commands used to run DeFlaky on this spec, with the local dashboard, in an MD file in the learning folder: the DeFlaky note.
When each agent runs, and where its output lands
Every run. Does the agent run every time the Playwright tests execute? Yes, the instructor said: it runs automatically whenever the Playwright run is done. The flow, as the instructor drew it: the Playwright tests run, the final output is a report, a results.json file, and then the custom reporter runs. The custom reporter calls DeFlaky, which runs twice, and puts the data into the HTML report. Similarly, it runs the RCA and the self-healing, and the data generator's output is pushed to it: in the end, the custom reporter calls the other agents, in the post-build actions.
Where each one really runs. The conclusion holds: every agent's output ends up in the custom report. The code splits the work, as the diagram shows. The Test Data agent runs inside the test and attaches its JSON (testDataAgent.ts, line 14). The self-healer runs in a fixture's teardown, after the test (test-base.ts, lines 137 to 141). Only the RCA agent runs in the reporter, in onEnd (CustomReporter.ts, line 476). DeFlaky runs outside the reporter: npm run flaky runs Playwright several times, and the wrapper writes the file the Flaky tab loads. And results.json is for DeFlaky: the custom reporter gets each result from Playwright's reporter calls, onTestEnd() and onEnd(), not from that file.
Locally, or in a GitHub pipeline? a learner asked. It will work with anything, the instructor said.
Forgot the branch? A learner forgot to create a new branch from the LLM gateway one. No worries, the instructor said: ask the AI to create a new branch for the new changes.
The self-healer: suggestions, not fixes
The flow. Whenever there is a failure, the self-healer captures the page, the page DOM. It gives it to the LLM gateway, the gateway gives suggestions, and the suggestions are available in the custom report. The deck has the flow:
Start the PW TestCase -> Failures -> Capture THE Page(DOM) -> LLM Gateway -> give suggestions -> CusTom Reporter appended.
The prompt. The deck's prompt for it:
here is the problem: I want you to create a new test case in the same AI test case as the E2E test case. What is happening here is that we want to add a self-healer AI agent by using the same agent factory concept. The concept here is that whenever a test case has run, if there are locator issues, we will capture the page where the failure happened because of a locator. That captured page we will send to the large language model, or LLM, and the LLM will suggest the respective self-healed locators automatically in the self-heal tab of a custom reporter. Can you create an end-to-end test case similarly in the AI test? Do the minimum changes. Whenever there is a failure of a locator, automatically we will pass it to the LLM gateway, and it will give the suggestion in the custom reporter if there is a failure. Please add this self-healer AI agent now. Also, make sure there is a separate prompt which is also added in the prompt.empty file in the prompts folder.
The spec. e2e-checkout-selfheal.spec.ts clicks a checkout button whose locator is deliberately stale:
/**
 * Self-Healer demo, built on the login fixtures from test-base:
 *   - The checkout button's data-test was "renamed" in this spec, so the click
 *     fails on a dead locator. The auto `selfHealer` fixture then captures the
 *     cart page, asks the LLM for replacement locators, verifies them against
 *     the live page, and shows them in the TTA report's Self-Heal tab.
 *   - The test still FAILS on purpose: the healer suggests, it never rewrites.
 */

import { test, expect } from '@fixtures/test-base';
import { visualStep } from '@utils/visualSteps';

// First product card on the TTACart inventory page.
const FIRST_ITEM_ID = 'test-allthethings-tshirt-red';

// DELIBERATELY STALE: the real button is [data-test="checkout"].
const STALE_CHECKOUT_BUTTON = '[data-test="checkout-button"]';
The step at lines 37 to 40 clicks it, with a 5-second timeout:
        await visualStep(page, 'Cart page: click checkout (stale locator)', async () => {
            await page.locator(STALE_CHECKOUT_BUTTON).click({ timeout: 5_000 });
            await checkoutStepOnePage.assertLoaded();
        });
The fixture. An auto fixture in test-base.ts runs the self-healer after every test, and it does work only when the test failed on a locator:
    // Runs for every test; only does work when the test failed on a locator.
    selfHealer: [async ({ page }, use, testInfo) => {
        await use();
        await healLocatorFailure(page, testInfo);
    }, { auto: true }],
The agent. selfHealAgent.ts says what it does in its header:
/**
 * Self-Healer agent.
 *
 * Runs after a test fails on a locator (wired as an auto fixture in test-base.ts):
 *   1. pulls the dead locator out of the Playwright error,
 *   2. captures the visible interactive elements of the page where it failed,
 *   3. asks the LLM (via the agent factory) for replacement locators,
 *   4. verifies each one against the live page (exactly 1 match, visible),
 *   5. attaches a HealReport as 'self-heal', which the TTA report's Self-Heal tab renders.
 *
 * It only suggests: the test still fails and no code is rewritten.
 */
Line 54 returns at once for a test that did not fail, and line 59 pulls the dead locator out of Playwright's call log, the waiting for locator(...) line; no locator, no LLM call. Then each candidate the model returns is checked on the live page:
        for (const c of candidates) {
            try {
                const locator = page.locator(c.selector);
                const matchCount = await locator.count();
                const visible = matchCount === 1 && (await locator.isVisible());
                if (matchCount === 1 && visible) {
                    report.verified.push({ ...c, matchCount, visible });
                } else {
                    report.rejected.push({
                        selector: c.selector,
                        reason: matchCount === 1 ? 'not visible' : `matched ${matchCount} elements`,
                    });
                }
            } catch {
                report.rejected.push({ selector: c.selector, reason: 'invalid selector' });
            }
        }
    } catch (e) {
        report.unavailableReason = (e as Error).message.split('\n')[0];
    }

    await testInfo.attach('self-heal', { body: JSON.stringify(report, null, 2), contentType: 'application/json' });
}
And its prompt, which asks for page.locator() strings, never getByRole(...) calls, so that every suggestion can be checked this way:
A Playwright locator failed. Suggest replacement locators for the element the test was trying to reach.

Test: {{TEST_TITLE}}
Action that failed: {{INTENT}}
Dead locator: {{FAILED_SELECTOR}}

Error:
{{ERROR}}

Page at the moment of failure:
URL: {{PAGE_URL}}
Title: {{PAGE_TITLE}}

Visible interactive elements on that page (JSON, one object per element):
{{ELEMENTS}}

Rules:
- Work out which element the dead locator was meant to find (its name, data-test value and the action are the best clues), then pick it from the element list. Never invent an element that is not in the list.
- Return 1 to 4 candidates, most robust first. Prefer, in this order: data-test / data-testid attributes, role with accessible name, label, id, visible text, then CSS.
- Every selector must be a string that Playwright's page.locator() accepts as-is, for example:
  [data-test="checkout"]   role=button[name="Checkout"]   text=Checkout   #checkout   button.checkout_button
  Do NOT return getByRole(...) or other method calls.
- Each selector must match exactly one element.
- strategy is one of: testid, role, label, text, css.
- reasoning: one short sentence on why this element is the one the test wanted.
The class's run. The instructor showed the test failing because of a locator, with its stack, and the Self-Heal tab: according to the self-healer, this is the locator that is problematic, and this is the possible answer you should be adding. The tab, in the report from 07:51:
should reach checkout step one (fails on a stale locator)
Dead locator: locator('[data-test="checkout-button"]') (locator.click)
Verified against the live page:
  [data-test="checkout"]   testid   1 match, visible
    The dead locator targeted the checkout button, and the actual checkout element on the page uses data-test="checkout".
  a.btn-primary   css   1 match, visible
    The checkout element is the primary-styled anchor linking to checkout-step-one.html, matching the intended checkout action.
  text=Checkout   text   1 match, visible
    The visible text 'Checkout' uniquely identifies the checkout link the test wanted to click.
Suggestions only. Nothing was rewritten.
The same report's AI Verdict tab had an RCA for this failure too, and its Flaky tab no flaky test: the test fails every time, so it is not flaky.
Will it fix the test? No, the instructor answered: it will just give you suggestions. The responsibility of the self-healer is a suggestion; it will not fix the test automatically. We can do that also, but that is a separate LangChain concept, the instructor said: if you want it to fix the test and run it, you have to create a separate LangChain agent. The instructor showed one, a Python agent, which can run in TypeScript too, since LangChain supports TypeScript. The integration in this framework gives suggestions, as of now.
No code by hand. These agents were totally added by AI, the instructor said: we have not coded anything at all. We took the framework and told the AI to add all this, with the help of Claude or GitHub Copilot.
Tasks and announcements
- CI/CD is next. Most of the things are done, the instructor said, and the agents are added: now it is time to run this in CI/CD, to push it into Jenkins as a job that runs daily, and to get an emailable report.
- The code is already pushed, the instructor said: commit bede915 on the llm-aiagents branch of the batch repo. When checked at 18:37 IST on 14 November, it was not merged into main yet. The agents are in src/ai/agents and the prompts in src/ai/prompts.
- The prompt: the instructor will share the agent factory prompt with the class. The deck's copy is quoted above.
- Exercise for today and tomorrow, and Cucumber BDD. The instructor asked everyone to do one exercise for today and tomorrow, and pointed to two tutorials. If you want to add Cucumber BDD on top of this Playwright framework, there are two lectures, part 1 and part 2, about two hours in all. They are extra, because not everyone wants to add Cucumber. They are in My Courses: the links were to be shared today and announced in the SDET group, and before the class ended, the instructor found both parts added.
- Next week: Jenkins and GitHub Actions. Next week's classes, all three of them (three to four, the instructor said first), set up Jenkins and GitHub Actions: how to set up Jenkins, how to run this same framework on Jenkins, and how to see the custom report in Jenkins or GitHub Actions. Make sure you complete them, very, very important, the instructor said: do not miss them.
- Then the last class: quality gates, taught by the instructor, for this advanced automation framework: how to follow coding standards, check the quality of the code, avoid AI slop, avoid over-engineering by using AI agents, do linting and type checking, secure your code, and make sure your Ponytail reviews are 100% ready. It will mark your Playwright framework and code readiness. The instructor showed how it will look: rules, and quality gates as Claude skills, such as AI slop, over-engineering and framework-pattern skills, to optimize this framework. The deck's list for it: code standard, quality of code, AI slop, avoid over-engineering (duplication), linting and typecheck, secure code (env, credentials), and Ponytail review.
- Not the end. When is the last class? It's all about learning, the instructor said: first complete the Cucumber part, the CI/CD part and the quality gates. That is going to be the last class, but there is no last class, to be honest, because we keep on learning.
- Homework: TTA chat. One more project, TTA chat, also needs to be automated; the instructor will give it as homework.
- The five-level challenges are ready too.
Self-healer will fix the test case also, right?
Worth practising too: How does the class's self-healer find the locator that failed? What has to be true before it lists a candidate as verified? Why does its prompt ask for page.locator() strings and not getByRole(...) calls?
Show the answer
Answer. No. The self-healer only gives suggestions, and the test still fails; to fix the test and rerun it, you need a separate LangChain agent. After a failed test, the selfHealer fixture's teardown reads the dead locator from Playwright's call log, the waiting for locator(...) line, and captures up to 150 visible interactive elements of the page as JSON. The agent asks the LLM for 1 to 4 candidates. Each one is verified only if page.locator(selector) matches exactly one element and that element is visible; anything else is rejected with the reason. The prompt asks for selector strings because a string can be passed to page.locator() as it is and checked automatically, while a method call cannot.
If there is no failure in the first build, will DeFlaky still run?
Worth practising too: What is a flaky test? How does DeFlaky decide that a test is flaky, and what is its FlakeScore? Why must retries stay 0 for a DeFlaky run, and why can 5 runs still miss a flaky test?
Show the answer
Answer. Yes. DeFlaky always executes, and with no failure it reports no flaky test: in its own report, zero flaky tests and a FlakeScore of 100%. A flaky test sometimes passes and sometimes fails across runs of the same code. DeFlaky runs the command several times, reads the JSON or XML report after each run, and sorts each test by its pass rate: 100% is stable, 0% is failing, anything in between is flaky. FlakeScore is stable tests divided by all tests, times 100, so one stable test out of two gives 50%. With retries, Playwright reruns the failed attempt, and DeFlaky sees fewer failures. And a test that fails half the time still passes five runs in a row about once in 32 tries, as one round in these notes did.
If an organization uses the Allure report, how can it link the RCA to it?
Worth practising too: What makes an agent in this framework? What happens when the model's reply breaks the agent's schema? When does the RCA agent run, and what does the AI Verdict tab show with no key?
Show the answer
Answer. Customize the Allure report, or create the RCA as a separate HTML report and append it to the Allure report, which has a way to append it. In this framework, an agent is a prompt file plus an output schema, passed to createAgent(); run(vars) fills the placeholders, adds the schema to the system prompt, calls the LLM gateway and checks the reply with AJV. A reply that breaks the schema makes run() throw, with AJV's errors and the raw JSON; analyzeFailure() catches it and falls back to a heuristic verdict. The RCA agent runs in the custom reporter's onEnd, after all the tests, once for each failed test, at most 10. With no key, the reporter skips it, and the AI Verdict tab says there are no verdicts.