What this class covered
- Why LangGraph after LangChain: a chain runs one way, a graph can decide
- State, nodes and edges, then compile and invoke
- Installing LangGraph in the chapter's own virtual environment
- Demo 1: the hello graph, and drawing any graph as Mermaid
- Demo 2: a linear pipeline, like setup, execute and teardown
- Demo 3: conditional routing: log a pass, file a bug, or quarantine
- Demo 4: a retry loop that tells flaky tests from broken ones
- Project: a Playwright flaky finder agent, built by vibe coding
- What comes next Saturday, and today's four battles
Why LangGraph after LangChain
LangGraph is an open-source Python library from the team behind LangChain, for building LLM applications as graphs: small functions connected by arrows.
A LangChain flow, as built in the last classes, runs one way: set up the LLM, set up the tools, execute, get a result. Step 1, 2, 3, 4. Real decisions do not work like that. Buying a home starts with choosing a location, and each choice opens more choices, like a tree. LangGraph lets an application work the same way. It can branch, loop, pause, resume, and wait for a human in the loop.
The testing example from class: a flaky test agent finds failures. If more than 10 tests fail, fail the build; if fewer, rerun them and try again. That fork is a graph.
Interview question: what is LangGraph? In the class notes: "LangGraph is a stateful graph orchestrator for LLM workflows. Nodes are functions, edges decide what runs next, and state is the shared memory that flows through them." Stateful means it remembers: what it has done so far, and which path it took to get here.
State, nodes and edges
- State is the single source of truth: one Python dictionary, whose shape you define, that travels through the whole graph. Every node reads it and returns only the keys it wants to change. Nothing is passed around by hand. You decide what goes in it: whatever the nodes need to share.
- A node is a plain function. It can call an LLM, run a tool, query a database, or just do an if/else in Python.
- An edge decides what runs next. A normal edge says "after A, run B". A conditional edge says "after A, look at the state and choose B, C or END". A loop is just an edge pointing backwards.
- compile() locks the graph, and invoke() runs it.
The class put it in plain English: the state is a backpack, like a child's school bag that everything goes into. A node is a worker, an edge is a decision, START and END are the doors, compile locks everything in place, and invoke hands in the backpack at the front door and collects it at the back.
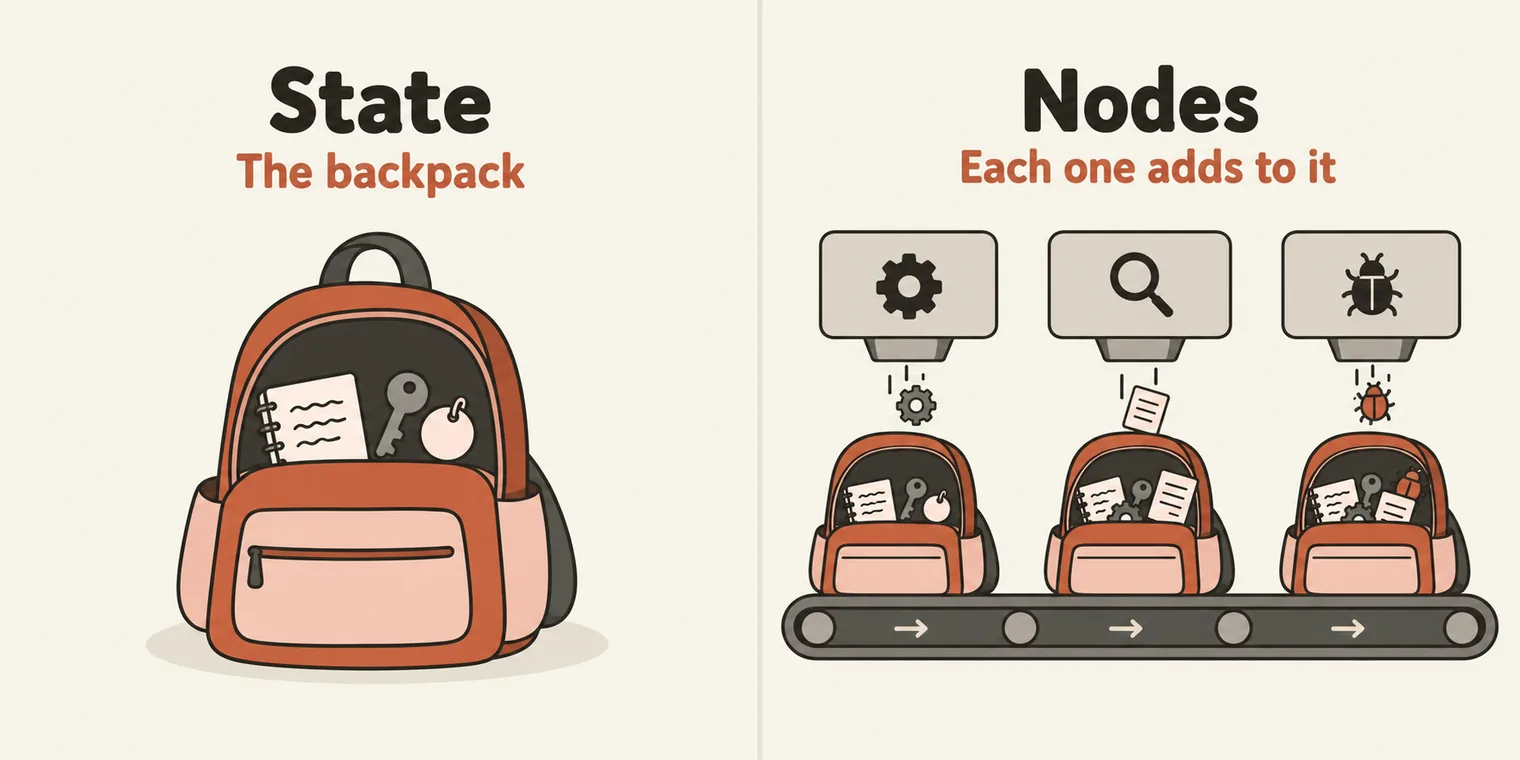
LangGraph is built for production, not demos: saving the state after every step, pausing for human approval and streaming are built in, because the state is explicit. Those come next Saturday.
Installing LangGraph
LangGraph comes from pip, as the LangGraph docs show:
pip install -U langgraph
Install it inside the chapter's own virtual environment, not for the whole project. Chapter 17 used LangChain; chapter 18 uses LangGraph. One project needs LangGraph and another does not, so each keeps its own environment and its own packages.
Demo 1: the hello graph
The smallest graph there is: one node between START and END.
from typing import TypedDict

from langgraph.graph import END, START, StateGraph

"""001 - The smallest possible graph: one node between START and END.
State is the backpack. A node is a plain function: it receives the backpack
and returns only the keys it wants to change. LangGraph merges them in.
"""

class State(TypedDict):
    tester: str
    greeting: str

def greet(state: State) -> dict:
    return {"greeting": f"Hello {state['tester']}, your first graph ran."}

builder = StateGraph(State)
builder.add_node("greet", greet)


builder.add_edge(START, "greet")
builder.add_edge("greet", END)

app = builder.compile()

if __name__ == "__main__":
    result = app.invoke({"tester": "Pramod"})
    print(result["greeting"])
    print("\nFinal state:", result)
    print("\nThe graph as Mermaid (paste into mermaid.live):")
    print(app.get_graph().draw_mermaid())
Hello Pramod, your first graph ran.

Final state: {'tester': 'Pramod', 'greeting': 'Hello Pramod, your first graph ran.'}

The graph as Mermaid (paste into mermaid.live):
---
config:
  flowchart:
    curve: linear
---
graph TD;
    __start__([<p>__start__</p>]):::first
    greet(greet)
    __end__([<p>__end__</p>]):::last
    __start__ --> greet;
    greet --> __end__;
    classDef default fill:#f2f0ff,line-height:1.2
    classDef first fill-opacity:0
    classDef last fill:#bfb6fc
- State is a
TypedDictwith two keys,testerandgreeting. A typed dictionary is a dictionary of key-value pairs, with the types written down. - greet is the only node. It reads the state and returns just
{"greeting": ...}; LangGraph merges that in. - The edges run from
STARTtogreetand fromgreettoEND. - compile() and invoke() run it with
{"tester": "Pramod"}.
There is no LLM here and no API key: the graph has no brain yet. It starts, does one thing, and stops.
Every graph can draw itself: app.get_graph().draw_mermaid() prints a Mermaid diagram, and pasting it into mermaid.live shows the picture. It works for any graph you build, a flaky finder or an RCA agent included, so you can see which decisions it can take.
In class, a graph was called "nothing but a linked list", which remembers the previous step and the next one. That fits a straight graph like this one. A graph can also branch and loop back, which a linked list cannot, and that is what the later demos add.
Demo 2: a linear pipeline
Three nodes in a row, the same lifecycle as a Playwright test: set up, run, clean up.
"""002 - Three nodes in a row, like a test's setup -> execute -> teardown.

Each node returns a *partial* update. Keys it does not return are left alone.
stream_mode="updates" shows you exactly what each node changed, step by step.
"""
"""
setup     changed -> {'browser': 'chromium'}
execute   changed -> {'status': 'passed'}
teardown  changed -> {'cleaned_up': True}


"""

from typing import TypedDict
from langgraph.graph import END, START, StateGraph


class State(TypedDict, total=False):
    test_name: str
    browser: str
    status: str
    cleaned_up: bool


def setup(state: State) -> dict:
    return {"browser": "chromium"}


def execute(state: State) -> dict:
    return {"status": "passed"}


def teardown(state: State) -> dict:
    return {"cleaned_up": True}


builder = StateGraph(State)
builder.add_node("setup", setup)
builder.add_node("execute", execute)
builder.add_node("teardown", teardown)


builder.add_edge(START, "setup")
builder.add_edge("setup", "execute")
builder.add_edge("execute", "teardown")
builder.add_edge("teardown", END)

app = builder.compile()

if __name__ == "__main__":
    for step in app.stream({"test_name": "login_works"}, stream_mode="updates"):
        for node, update in step.items():
            print(f"{node:<9} changed -> {update}")

    print("\nFinal state:", app.invoke({"test_name": "login_works"}))
setup     changed -> {'browser': 'chromium'}
execute   changed -> {'status': 'passed'}
teardown  changed -> {'cleaned_up': True}

Final state: {'test_name': 'login_works', 'browser': 'chromium', 'status': 'passed', 'cleaned_up': True}
What the three stages share is the state: every node can see the test name, the browser, the status and whether clean-up ran. stream_mode="updates" prints what each node changed, step by step. A straight line like this, LangChain could do too. The shared state is what is new.
Demo 3: conditional routing
After a task, the agent has a decision to make, and this is where LangGraph excels. A Playwright result comes in: if it passed, log it; if it failed, file a bug; if it is flaky, quarantine it.
"""003 - A fork in the road: route a test result to the right next step.

add_conditional_edges(source, router, destinations)
The router is a normal function that reads state and returns the NAME of the
next node. That one function is where an "agent" makes decisions.
"""

from typing import Literal, TypedDict
from langgraph.graph import END, START, StateGraph


class State(TypedDict, total=False):
    test_name: str
    status: str          # passed | failed | flaky
    action: str

def read_result(state: State) -> dict:
    return {}            # in real life: parse a Playwright report here


def route_by_status(state: State) -> Literal["log_pass", "file_bug", "quarantine"]:
    return {"passed": "log_pass", "failed": "file_bug"}.get(state["status"], "quarantine")


def log_pass(state: State) -> dict:
    return {"action": "logged as green"}


def file_bug(state: State) -> dict:
    return {"action": f"Jira bug filed for {state['test_name']}"}


def quarantine(state: State) -> dict:
    return {"action": f"{state['test_name']} moved to quarantine, rerun nightly"}


builder = StateGraph(State)
builder.add_node("read_result", read_result)
builder.add_node("log_pass", log_pass)
builder.add_node("file_bug", file_bug)
builder.add_node("quarantine", quarantine)

builder.add_edge(START, "read_result")
builder.add_conditional_edges("read_result", route_by_status,
                              ["log_pass", "file_bug", "quarantine"])
for leaf in ("log_pass", "file_bug", "quarantine"):
    builder.add_edge(leaf, END)

app = builder.compile()

if __name__ == "__main__":
    for name, status in [("cart_total", "passed"),
                         ("checkout_pay", "failed"),
                         ("login_redirect", "flaky")]:
        out = app.invoke({"test_name": name, "status": status})
        print(f"{name:<15} {status:<7} -> {out['action']}")

    print("\n" + app.get_graph().draw_mermaid())
cart_total      passed  -> logged as green
checkout_pay    failed  -> Jira bug filed for checkout_pay
login_redirect  flaky   -> login_redirect moved to quarantine, rerun nightly

---
config:
  flowchart:
    curve: linear
---
graph TD;
    __start__([<p>__start__</p>]):::first
    read_result(read_result)
    log_pass(log_pass)
    file_bug(file_bug)
    quarantine(quarantine)
    __end__([<p>__end__</p>]):::last
    __start__ --> read_result;
    read_result -.-> file_bug;
    read_result -.-> log_pass;
    read_result -.-> quarantine;
    file_bug --> __end__;
    log_pass --> __end__;
    quarantine --> __end__;
    classDef default fill:#f2f0ff,line-height:1.2
    classDef first fill-opacity:0
    classDef last fill:#bfb6fc
add_conditional_edges("read_result", route_by_status, [...]) hands the decision to route_by_status, an ordinary function that reads the state and returns the name of the next node. In the Mermaid output, the conditional edges show as dotted arrows, -.->. Who marks a test as passed or failed? Playwright, in its report.
The other functions are stand-ins to show the shape. In real life read_result parses a Playwright report, file_bug calls the Jira API, and a pass would be marked through an API call too.
Demo 4: a retry loop
An edge can point back to an earlier node, and that makes a loop. Every loop needs a cap, like Playwright's retries: rerun a failing test up to three times.
from typing import Literal, TypedDict
from langgraph.graph import END, START, StateGraph
MAX_ATTEMPTS = 3

class State(TypedDict):
    test_name: str
    scripted_outcomes: list[str]   # what each attempt will return (simulation)
    attempts: int
    history: list[str]
    verdict: str

def run_test(state: State) -> dict:
    n = state["attempts"]
    outcome = state["scripted_outcomes"][n]
    print(f"   attempt {n + 1}: {outcome}")
    return {"attempts": n + 1, "history": state["history"] + [outcome]}

def should_retry(state: State) -> Literal["run_test", "report"]:
    if state["history"][-1] == "passed":
        return "report"
    if state["attempts"] < MAX_ATTEMPTS:
        return "run_test"          # <- the loop
    return "report"

def report(state: State) -> dict:
    h = state["history"]
    if h[-1] == "passed" and "failed" in h:
        verdict = f"FLAKY: passed on attempt {len(h)} after {h.count('failed')} failure(s)"
    elif h[-1] == "passed":
        verdict = "STABLE PASS"
    else:
        verdict = f"REAL FAILURE: failed all {len(h)} attempts"
    return {"verdict": verdict}

builder = StateGraph(State)
builder.add_node("run_test", run_test)
builder.add_node("report", report)


builder.add_edge(START, "run_test")
builder.add_conditional_edges("run_test", should_retry, ["run_test", "report"])
builder.add_edge("report", END)

app = builder.compile()

if __name__ == "__main__":
    scenarios = {
        "login_redirect (flaky)": ["failed", "failed", "passed"],
        "checkout_pay (broken)": ["failed", "failed", "failed"],
        "cart_total (stable)": ["passed"],
    }
    for name, outcomes in scenarios.items():
        print(name)
        out = app.invoke({"test_name": name, "scripted_outcomes": outcomes,
                          "attempts": 0, "history": [], "verdict": ""})
        print("   =>", out["verdict"], "\n")
login_redirect (flaky)
   attempt 1: failed
   attempt 2: failed
   attempt 3: passed
   => FLAKY: passed on attempt 3 after 2 failure(s)

checkout_pay (broken)
   attempt 1: failed
   attempt 2: failed
   attempt 3: failed
   => REAL FAILURE: failed all 3 attempts

cart_total (stable)
   attempt 1: passed
   => STABLE PASS
should_retry is the conditional edge. A pass goes to the report; a failure goes back to run_test until MAX_ATTEMPTS runs out. The outcomes here are scripted, so the demo is repeatable.
A plain Python loop could retry too. The difference is the state: every attempt is written into history, so the report can tell a test that failed and then passed (flaky) from one that failed every time (a real failure). LangGraph can also put a person in the loop before a bug is filed, to review it first.
Project: a Playwright flaky finder
To finish, the class vibe-coded a small project from the same pieces: a graph that runs real Playwright tests by itself, reads the result, and decides whether to rerun. The objective, in the repo's words: "For valid and invalid test cases it reads that result, and based on the result it decides whether it has to rerun or not."
r"""Project - a retry loop around REAL Playwright tests.

Lesson 004 scripted its outcomes so the demo was repeatable. This runs the real
thing: pytest drives Chromium against TTACart, writes a JUnit report, and the
graph reads that report to decide what to do next.

    run_tests -> read_report -> should_retry? --(failures left)--> run_tests
                                             \--(done)----------> summarise

Only the failed tests are re-run on a retry, which is what you would do by hand.
A test that passes on attempt 2 is FLAKY. One that fails every attempt is a REAL
FAILURE. That distinction is the whole point of the loop.

    .venv/bin/python3.13 src/Project_PW_FlakyFinder.py
"""
import subprocess
import xml.etree.ElementTree as ET
from pathlib import Path
from typing import Literal, TypedDict

from langgraph.graph import END, START, StateGraph

MAX_ATTEMPTS = 2                       # 1 run + 1 retry. Raise this for more.
HEADED = True                          # watch the browser. False is faster in CI.
SLOW_MO_MS = 600                       # slow each action down so it is followable.
HERE = Path(__file__).parent
TESTS = HERE / "tests" / "test_login.py"
REPORT = HERE / "report.xml"
PYTHON = HERE.parent / ".venv" / "bin" / "python3.13"   # 3.12 in this venv has no pytest


class State(TypedDict):
    attempts: int
    failed: list[str]          # test ids still red after the last attempt
    history: list[dict]        # one entry per attempt
    verdict: str


# ---------------------------------------------------------------- nodes
def run_tests(state: State) -> dict:
    """Run pytest. On a retry, run ONLY the tests that failed last time."""
    attempt = state["attempts"] + 1
    targets = state["failed"] or [str(TESTS)]
    print(f"\n-- attempt {attempt}: pytest {' '.join(Path(t).name for t in targets)}")
    watch = ["--headed", f"--slowmo={SLOW_MO_MS}"] if HEADED else []
    subprocess.run(
        [str(PYTHON), "-m", "pytest", *targets, *watch, f"--junitxml={REPORT}", "-q"],
        cwd=HERE.parent, capture_output=True, text=True,
    )                                   # exit code ignored: the report is the truth
    return {"attempts": attempt}


def read_report(state: State) -> dict:
    """Parse the JUnit XML pytest just wrote. This is the agent's only evidence."""
    passed, failed = [], []
    for tc in ET.parse(REPORT).getroot().iter("testcase"):
        test_id = f"{TESTS}::{tc.get('name')}"
        broke = any(c.tag in ("failure", "error") for c in tc)
        (failed if broke else passed).append(test_id)
    for t in passed:
        print(f"   PASS  {t.split('::')[-1]}")
    for t in failed:
        print(f"   FAIL  {t.split('::')[-1]}")
    entry = {"attempt": state["attempts"], "passed": passed, "failed": failed}
    return {"failed": failed, "history": state["history"] + [entry]}


def should_retry(state: State) -> Literal["run_tests", "summarise"]:
    """The conditional edge. Pointing back at run_tests is what makes it a loop."""
    if not state["failed"]:
        return "summarise"
    if state["attempts"] < MAX_ATTEMPTS:
        return "run_tests"
    return "summarise"


def summarise(state: State) -> dict:
    """Compare every attempt to tell a flaky test from a broken one."""
    ever_failed = {t for h in state["history"] for t in h["failed"]}
    still_failing = set(state["failed"])
    lines = []
    for test in sorted({t for h in state["history"] for t in h["passed"] + h["failed"]}):
        name = test.split("::")[-1]
        if test in still_failing:
            lines.append(f"REAL FAILURE  {name}  (red in all {state['attempts']} attempt(s))")
        elif test in ever_failed:
            lines.append(f"FLAKY         {name}  (failed, then passed on retry)")
        else:
            lines.append(f"STABLE PASS   {name}")
    return {"verdict": "\n".join(lines)}


# ---------------------------------------------------------------- graph
builder = StateGraph(State)
builder.add_node("run_tests", run_tests)
builder.add_node("read_report", read_report)
builder.add_node("summarise", summarise)

builder.add_edge(START, "run_tests")
builder.add_edge("run_tests", "read_report")
builder.add_conditional_edges("read_report", should_retry)   # <- the loop lives here
builder.add_edge("summarise", END)

app = builder.compile()

if __name__ == "__main__":
    result = app.invoke({"attempts": 0, "failed": [], "history": [], "verdict": ""})

    print(f"\n{'=' * 60}\nVERDICT after {result['attempts']} attempt(s)\n{'=' * 60}")
    print(result["verdict"])

    print("\nThe graph as Mermaid (paste into mermaid.live):")
    print(app.get_graph().draw_mermaid())
The two tests log in to TTACart, the Testing Academy's practice shop: one with valid details, one with junk ones. The second asserts that the login succeeded, so it fails every time, on purpose. The tests themselves, from the full file in the repo:
def login(page: Page, username: str, password: str) -> None:
    page.goto(URL)
    page.locator("#user-name").fill(username)
    page.locator("#password").fill(password)
    page.locator("#login-button").click()


def test_valid_login(page: Page) -> None:
    """Correct credentials land on the products page. This one should pass."""
    login(page, VALID_USER, VALID_PASS)
    expect(page).to_have_url(re.compile(r"/inventory"))
    expect(page.get_by_text("Products")).to_be_visible()


def test_invalid_login(page: Page) -> None:
    """Wrong credentials. Asserting success here, so this ALWAYS fails."""
    login(page, BAD_USER, BAD_PASS)
    expect(page).to_have_url(re.compile(r"/inventory"))
Running it, headless here (the repo's version opens the browser so you can watch):
-- attempt 1: pytest test_login.py
   PASS  test_valid_login[chromium]
   FAIL  test_invalid_login[chromium]

-- attempt 2: pytest test_login.py::test_invalid_login[chromium]
   FAIL  test_invalid_login[chromium]

============================================================
VERDICT after 2 attempt(s)
============================================================
REAL FAILURE  test_invalid_login[chromium]  (red in all 2 attempt(s))
STABLE PASS   test_valid_login[chromium]

The graph as Mermaid (paste into mermaid.live):
---
config:
  flowchart:
    curve: linear
---
graph TD;
    __start__([<p>__start__</p>]):::first
    run_tests(run_tests)
    read_report(read_report)
    summarise(summarise)
    __end__([<p>__end__</p>]):::last
    __start__ --> run_tests;
    read_report -.-> run_tests;
    read_report -.-> summarise;
    run_tests --> read_report;
    summarise --> __end__;
    classDef default fill:#f2f0ff,line-height:1.2
    classDef first fill-opacity:0
    classDef last fill:#bfb6fc
- The agent runs the tests, not you.
run_testsstarts pytest withsubprocess, and the graph takes it from there. - The report is the only evidence. The exit code is ignored;
read_reportparses the JUnit XML, and that is where an LLM node would plug in later. - Retries rerun only what failed. Attempt 2 runs one test, not the whole file, as you would by hand.
MAX_ATTEMPTS = 2means one run plus one retry. - There is no LLM yet. Every decision is a plain condition. The class's phrase for where this is heading: agentic QA, where agents decide which tests to run, which passed and how many failed.
To run it yourself, from chapter_18_LangGraph, with LangGraph, pytest and pytest-playwright installed in its virtual environment:
.venv/bin/python3.13 src/Project_PW_FlakyFinder.py
A real framework can take the place of the two-test script. The repo's write-up of the project walks through the state and the design decisions.
What comes next Saturday
One more LangGraph class, the last one, to finish the flaky test case analyzer:
- running branches in parallel, for example UI tests and API tests separately;
- checkpoints, to keep the state in memory;
- a human in the loop, for approvals;
- an LLM making the decisions instead of fixed conditions;
- the final project: a flaky test case analyzer that uses an LLM to check what a person used to check by hand.
Tasks and announcements
- This was not the last class. One more LangGraph class follows next Saturday.
- This Friday: the MCP session. Join it.
- Another hackathon is coming.
- The class notes are being shared.
Task 1, the four battles. Today's battles cover CrewAI, CrewAI tools, LangChain and the agent executor; start with the CrewAI quiz. Create a free account with your LinkedIn, finish all four today (it takes under an hour), and post your results in the SDET Club.